Friday, 15 April 2016

Releasing Applications as Native OS Packages

Agility when building, testing, packing and deploying Software  is certainly a key quality aspect to pursue. BTW, there is no specific recipe to get there, among several other things that needs to done, avoid manual steps and not reinvent the wheel  by relying on well established solutions on the community are some of them. Going on this direction, there is very interesting project maintained by Netflix that is called Nebula.

Nebula Project is a series of individual Gradle plugins, each focused on providing a very specific functionality in an usual Development Pipeline tasks. Today I'm gonna talk about one of those, nebula-os-package.

The main idea

The main idea behind It is to pack a JVM based application and Its metadata as a native OS package. The plugin is able to generate Deb and RPM packages, which are the most popular package formats on the Linux world.

Using


First of all, add the plugin on your build.gradle file.


Then, add the specify the plugin dependency

Now you need to say how the application is gonna be set on Host, after the package is installed.

Couple of important things that are happening here:
  • Specifying package name and version (lines 2 and 3)
  • Under which directory the package is gonna be placed after installed on the target Host (line 5).
  •  All jars produced by Gradle during the build (the application jar and Its dependencies), are gonna be placed under /opt/packageName/lib on the target Host. (line 8)
  • Same thing  for configuration files under the resource folder (line 18).
  • The scripts generated by Gradle when building a Java application are gonna be used to start It up on the target Host (line 11).
With everything property set, just execute the build command accomplished by the package task specified on the build file.  The Debian package is gonna be placed at projectName/build/distributions

So What?


Someone could be arguing: 
  • Why should I use this? 
  • Is It better than build a  Fat jar with all Its dependencies inside! 
  • Gradle application plugin takes care of the whole Application start up for me generating  useful scripts.
Yes, these are all valid points. Actually, this is the way we've being done so far when releasing applications outside of the J2EE world. But doing like this tasks like: deploy, start/stop, update and removing applications are all on you. Scripts will need to be create to manage all these, so one more thing that Ops and Dev teams will need to care about.
When deploying applications as Native OS packages,  you can leverage a whole set of tools that are already there and none of the scripts mentioned before would be needed. This is a valid point when that affects agility when releasing and maintaining software.

Here  I have a working example in case you wanna try It out.

Cheers,


Friday, 8 April 2016

Google Pub/Sub. An Alternative Tool for Data Ingestion.

Less than one year ago, Google launched officially on the market a new cloud messaging service,  Google Pub/Sub. I've to confess I just looked at It more carefully after reading a very nice Blog post made by Spotify engineering team, describing their experience when testing this service.
As the name suggests, the processing model is based on  the publishing/subscribing, pattern implemented by most of the best brokers available on the market.
The message consumption works in two models:
  • Polling: You can configure your client o poll the topics times to times. 
  • Push: You register an URL that the Google Pub/Sub service is gonna call when messages arrive to the topic (web hook like)

Besides that, here are some characteristics that, in my opinion, makes this tool an interesting solution:

Durability

Messages sent to Google Pub/Sub messing system  wont be lost lost. Google guarantee message retention up to  7 days, which pretty resealable. This is a must in scenarios where back pressure needs to implemented and some other consistency requirements needs to be attended.


Reliability 

The Google Pub/Sub  messaging service is available in almost all regions where their cloud service is working (North America, Europe and Asia). The advantage here is, Multi Region availability and replication. It is all google responsibility keep everything in sync and available for you. The operational costs to make systems like this work on promise are sky high, so rely on a third party service is a very relevant point to consider.


Low Latency and High Throughput

Results shown by the Spotify Engineering team and the Google documentations itself are  very enthusiastic (1M messages/second). That makes It a considerable option for near real time processing systems. We should never trust 100% on benchmarks, ideally we should try It by ourselves, but similar number are on the Google documentation also, so It's relevant.


APIs

Choose your flavor

  • Java
  • Python
  • Objective C
  • GO
  • PHP
  • Javascript
  • REST
Once you pick one, It's resealable to check the performance to be sure It meet your needs. The Spotify team had some issues with the Java API, so they move to REST.

Billing model

It looks pretty fair ($0.40 /million messages on the first 250M). Just be aware that the real cost is gonna consider also:
  • Number or API calls: The process of sent, consume and ack a message are considered 3 separated API calls. The massage size is also taken into account. Google charges by blocks of 64 KB, so if the message contains 128 KB It's gonna take 2 calls.
  • Storage
  • Network
So, the final price may be tricky to calculate. Be aware that It may cost more than you expect It be.

When talking about data ingestion, this is definitively a tool to keep on the radar. The comparison with Apache Kafka is inevitable at this point, but in my opinion they are similar in some aspects but differ in others:

  • They are both production ready for Real time Log Analytics. There are several benchmarks on the Web using both and showing they are robust alternatives. BTW, Apache Kafka is more time on the market, which gives It some advantage.
  • They differ on the processing model. Differently than Kakfa, Google Pub/Sub doesn't let consumers rewind back  on the topic. On this point, Google Pub/Sub works more like a traditional messaging system (without the overheads).  Before being released as a product, Google Pub/Sub was a tool used internally by Google team and they didn't have this requirement so far. BTW, I won't be surprised seeing this feature on the next releases.
In my opinion, the ability to reprocess messages in a topic makes Apache Kafka a more relevant option when implementing Kappa Architecture. BTW, It's always interesting see another option for data ingestion on the market. More use cases would definitely make It more popular.

There is some producer example here. Google lets you use this service for free during 60 days. which is awesome for POCs in case you wanna try It.

Cheers,


Monday, 3 August 2015

SOA/MSA design - Isolating contract dependencies

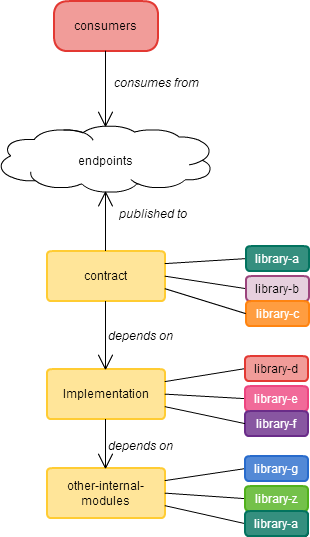
Contract is a crucial part of any services anatomy. In a SOA/MSA approach, contracts exposes the services behaviour that consumers will rely on. This behaviour is usually exposed as series of interfaces and input/output structures and implemented by internal components. The last is usually hidden from external consumers. The previous described structure may look like this:


On this example, modules are splitted, there is only one dependency flow (internal modules doesn't know external ones), each module has Its own set of dependencies, consumers rely on abstractions (the contract), so far so good.
When consuming services through REST or SOAP, consumers will need to serialise and deserialise the structures service exposes. It means they will need to hold a copy of these structures locally in order to get this job done. Now lets say you want to avoid this structure replication through all consumers inside your company. Considering services are built following the structure illustrated before, the contract module could be splitted apart and then shared with the consumers. In this scenario, you may get ride of the structure replication issue, but will running into another. When issuing the contract module as is to consumers, they will now depend on the same libraries that contract depends, otherwise consumers wont be able to use them. What about services moving to a different library-A version that isn't compatible with previous ones? A scenario like this:


If all consumers don't upgrade to the same library-A version than service is they will be broken. More consumers you have on this model, more synchronisation between them will be needed to deploy. More services you have worst It get. The expected agility when choosing this architecture approach will be harder to achieve.
One possible solution for this problem is, accept that consumers will hold local copies and just deal with It. Accepting they will have some extra work is still better than the coupling scenario described before.
You can also design your service keeping the contract module with less dependencies as possible. It may looks like this:


This design guideline can increase services flexibility when sharing contract as library. Consumers would need be affected only contract behaviour changes.even here but there are techniques to mitigate these effects. It is also an example that being succeed on going for SOA/MSA approaches depends also on good design and architectures choices.


Sunday, 28 June 2015

AWS-Lambdas - Automating function deploys

On this post, I talked about the ideas behind AWS-Lambdas computation service and how It works.The presented example shows how It can be be deployed and used. Even having an working example, there is an issue on the way I'm using It. All steps regarding the deploy process are manual. It just goes against agility. Manual deploys as such are error prone. More complex the application get, more expansive It will be to maintain.The side-effects when maintaining manual deploy steps are endless, so there should be an alternative to automate It and make AWS-Lambdas really cost effective as It promises to be.
Kappa seems to fill this gap. It is a command line tool that greatly simplifies the process of having lambdas deployed on the cloud. All steps described on the mentioned post can be automated. Now are talking!

Setup

Before start, be sure you have python (2.7.x)  and pip available on the command line.

Installing kappa: 

I strongly advice build It from sources as far there are important bug fixes that seems to be fixed recently:

git clone https://github.com/garnaat/kappa.git
cd kappa
pip install -r requirements.txt
python setup.py install

Instaling awscli:


sudo pip install awscli


Configuration:

First thing to do is create the the kappa configuration file. This is where I'm gonna tell It how to deploy my lambda function (config.yml).
---
profile: my-default-profile
region: us-west-2
iam:
  policy:
    name: AWSLambdaExecuteRole
  role:
    name: lambda_s3_exec_role
lambda:
  name: myLambdaFuncId
  zipfile_name: integrator.zip
  description: Somethhing that helps describe your lambda function
  path: src/
  handler: Integrator.handler
  runtime: nodejs
  memory_size: 128
  timeout: 3
  mode: event
  test_data: input.json
  event_sources:
    -
      arn: arn:aws:s3:::[set your bucket name]
      events:
        - s3:ObjectCreated:*


Lets see what is going on:

Line 2: There should be a profile that kappa will use to authenticate Itself on amazon and create the function in my behalf. We are gonna see it later on the awscli  configuration;
Line 4: The policies assigned to this lambda. In case they aren't there yet, kappa will create them for me.
Line 9 - 18: function Runtime configs.
Line 19: This is the file that contains an example request in order to test the function. It is useful once we want to be sure everything is working fine after the deploy is over.
Line 20: Here I'm setting from where events will come from. In this case, any changes on the given bucket, will trigger a call to my function.

Now It's time to configure aws-cli. The only configuration needed is the security profile. Kappa will use It as stated before:

Create the following file in case Isn't already there: ~/aws/credentials and put the following content
[my-default-profile]
aws_access_key_id=[YOUR KEY ID ]
aws_secret_access_key=[YOUR ACCESS KEY ]


Having it set, It's time to deploy it using kappa tasks:
kappa config.yml create
kappa config.yml add_event_source
kappa config.yml invoke
kappa config.yml status


It should be enough to see the function deployed on the aws-console. The previous commands in order did:

  • create the function on the amazon
  • Make it listen changes on a given bucket
  • Test the deployed function using fake data (simulating an event)
  • Check the status of the deployed function on amazon.


As far Kappa let me automate all deploy tasks,I'm able to create a smarter deploy process. I worked in an example about how could It be done here. I may forgot to mention some detail about the process of having It work, so in this case leave me message and I'll be glad to help.


Sunday, 7 June 2015

AWS Lambda - Computation as Service

Less than one year ago, Amazon launched  a new computation service, the AWS-Lambda. It promises simplify the process of building applications, by hosting and running code for you.  All the infrastructure and some scalability and fail over aspects are Amazon's concerns. It also integrates pretty well with other Amazon's services like SQS, SNS, DynamoDB, S3, etc. The code hosted there can even be called externally by other applications using the aws-sdk.

Here, I'll show how to use this service by doing something very simple. It idea is implement some code that will listen to an event (PUT) in a given S3 bucket, apply some processing on the file content, and send It to a SQS Queue.

This service restricts the language and platform where the code is implemented. A NodeJS module needs to be exported and called after deployed into the Amazon infrastructure, So, if you are not familiarised with Javascript and Nodejs, I would advice you to step back and look some documentation first.

var AWS = require('aws-sdk');
var parser = require('xml2js').parseString;
var async = require('async');

var s3 = new AWS.S3();
var sqs = new AWS.SQS();

exports.handler =  function(event, context) {
 var bucketName = event.Records[0].s3.bucket.name;
 var fileName = event.Records[0].s3.object.key;

 async.waterfall([
  function download(next) {
   s3.getObject({Bucket: bucketName,  Key: fileName}, function (err, data) {
    next(err, data);
   })
  },
  function parseXml(response, next) {
   parser(response.Body.toString(), function(err, result) {
    next(err, result);
   })
  },
  function sendMessage(result, next) {
   var message = {
    MessageBody: JSON.stringify(result),
    QueueUrl: "[YOUR QUEUE URL: i.e: https://....]"
   };
   
   sqs.sendMessage(message, function(err, data) {
      if(err) {
         context.fail("Error: " + err);
       } else {
         context.succeed("Message sent succefully: " + data.MessageId);
       }
       context.done();
   });
  }
 ], function(err) {
  if (err) {
   context.fail("Error: " + err);
   throw err;
  }
 });

}

Lets see what is happening here:

  • From line 1 to 3: Importing the modules needed on the implementation. All these modules needs to be packed when deploying the application, except by the aws-sdk, which is available by default in runtime.
  • Line 9 and 10:  Getting information from the event. When listing to an event from a S3 bucket, what you receive is the event metadata. So, if you want to do something with the object that uploaded, you need to extract the event metadata and then get the uploaded object and do something with the content.
  •  Line 12: The code from this point is a series of callbacks that depends from each other's results. So, to avoid the callback hell scenario, I used an external lib that make these functions dependencies a bit more clear to read.
In order to sure It's everything ok before deploying It, go to the console and perform a "npm install" command. It should check all code dependencies and put them into a specific directory.

Now It's time to set It up on Amazon infrastructure. The AWS-Lambda service let you upload a zip file with Its dependencies inside a Zip file. When using this option, be careful when creating the zip file. The Javascript file that will contains the code shown before needs to be at "/" on the zip file, otherwise It wont work. Worst than that, when running the code, the error message on the console is gonna show an error message that does not point on this direction.

Once is you have your code properly packed, go to the AWS console, access the "Lambda" option and and ask to create a new function. The  presented screen should look like this:


There, I'm putting basic information about what I'm uploading. The most relevant information are the Handler (Javascript file + the module name to be called) and Memory and Timeout values (Amazon will use this information billing). There is still the execution role. If you don't have one yet, create It using the options available on the combo box.  Once you managed to finish this step, the module is ready to be called. Now, the last step is just go to the bucket and I'm interested to monitor, and trigger this this function every time a new event happens by changing the bucket properties.

An additional and reasonable step would be test this deployed function in order be sure It's everything ok. In order to do that , go the console where all the functions are listed, select the function you want to test, press the "Actions" and select "Edit/Test". A new screen will be  presented. On the left side, there is a section called "Sample Events". It simulates some real use cases. To test this function, pick "S3 Put" option and  adapt the event setting valid bucket and file names. 
If everything went fine, you should able see a message looking like this on the Execution result area:

"Message sent successfully: 9431465....."

Some additional billing information should be displayed also and that is It. From this point you are sure that the function is properly deployed and ready to be used.
The working example can be found here.

Sunday, 10 May 2015

Devops Culture - Why Silos are an issue?

Devops is becoming a hot subject nowadays. There are some nice materials here and here explaining the principles behind It. At this point, we know that Deveops isn't only about automation tools and frameworks. It's about a different way to thing I.T, One of these principle is the Culture.
This is actually an essential dimension when talking about changing the way companies build software. They can pick the best automation tools available or hire the best market consultants to built their architecture, but if cultural aspects aren't improved, they may wont ship software as they expect. Today I'm gonna talk about one these cultural aspects, the Silos.


The Traditional Division


It's very commons see companies splitting up teams by their skills. A traditional division that follows this idea would look like that:


On this model, the software creation will be supported by a series of  specialised teams. These teams will "somehow" be talking to each other in order to build a solution. Using this structure, companies can have specialists on each that will lead people, ensuring issues/solutions are addressed properly. This structure can change a bit depending on the case. There are cases where companies nominate people to supervision (manage) to whole pipeline. They can be responsible by make everybody talk, that environments are delivered on schedule, issues are addressed by the right people/groups, etc.
Software has been delivered on top of this model during years. But we're living in a different era now and there are some scenarios this model does not handle well.

The Software Complexity


The problems we need to solve with software today are different than the ones we needed 10 years ago. Lets see some examples that illustrate this:

  • The data volume systems need to handle is way bigger than before. Architectural decisions need to take place in order to build systems that met business expectations. Such decisions can even change the way business sells their products to Its consumers.
  • The decision of moving to the cloud or not is today a strategic business decision not from some geek on the ops area. 
  • Solutions needs to support traffic growth in terms of seconds. Systems need to be elastic, but architectural decisions can make it impossible to achieve. Ops and arch teams need to be on the same page here before take any architectural decision.
  • How to test a solution with the characteristics  as highlighted before? QA team will need special skills.

Teams needs to be on the same page since the beginning here. Even small decisions can affect everybody's and make the release process slower release after release as far  application grows. What happens with the traditional model is that people tend to ignore the software complexity as whole and focus the area where they are experts. People  can workaround this issue and achieve the necessary coordination even on the traditional model, BTW, It is gonna demand more effort from everybody involved.
The complexity is well handled when people understand the system as whole. Adding barriers between teams does not help achieve this goal.

The Barriers Between Teams


When workstreams are used as silos, the development cycle is over simplified. Software is treated as a simple package that could be sent here and there. The issue is that the whole software complexity described before is ignored. As the complexity grows, releases  and maintenance start take more time and then became more expansive.  When dealing with complex software,  communication, alignment and proper architectural understanding are essential to support the whole process. The barriers created due oversimplification wont help on this scenario. Companies tend to normalise the communication between teams in  order to reduce misunderstanding but they actually just add more noise. The idea behind "breaking Silos" is remove the barriers to let people collaborate and then understand the system as whole.

As more barriers are created between business and production less agile the development cycle will be. Does not matter how many experts are on each Silo or how many automation tools they implement, The barriers between them will be always something to improve. By removing Silos, people are able to see the system as whole rather than only their "working-area". The real benefits became when system is optimised as whole instead of specific parts.

Saturday, 2 May 2015

Apache camel - Testing integrations

As far Systems are became more complex, It turns out that Test Automation is a mandatory Software Engineering discipline that needs to be followed. It is specially true when talking about Integrations between systems.On such scenarios, there are some challenges
  • Hard to isolate components - to test a single component, call to other components may need to be made in order to make the test possible, which makes the test process expansive
  • How to simulate system failures -  How to test the implementation behaviour in case one of the system being integrated fails? It is gonna be complicated or at least very time consuming simulate this test scenario because we need to control components that we usually can't.
  • Slow Build  - calls to external systems can be slow (slow connection, external system unavailability, etc). If your tests are build calling external systems, the build time might get slower over time as far you test coverage grows.
At the end of the day, these are things we need to workaround because tests would need to be done anyway. The good news is that It is possible to achieve certain level of test coverage even  on such scenarios. By using some DI techniques and a couple of frameworks I'm gonna make it happen.
I'm gonna use my last post as base. Actually I'll keep It as It is and create a different implementation applying modifications that will let It testable.

What is worth to test?


Looking to the implementation as It were, would be desirable test if the routing logic works as we expect on both cases (when it finishes successfully and when there is an error). To achieve that, I don't necessarily need  to rely on Amazon S3 or a different external component. I can "mock" them and then test the routing logic isolatedly.

How to do that?


In order to not depend on Amazon S3 on my tests, I need somehow  "replace" It only during the tests by "mocked" endpoints. By doing that, I'll be able to isolate what needs to be tested (the routing logic) and also control the input data, then simulate the behaviour I want.
First thing to do is to remove the hard coded references to S3 externalising them. The code will look as follows:

 @Component
class FileRouter extends RouteBuilder {
  @Autowired val sourceJsonIn: String = null
  @Autowired val targetJsonOut: String = null
  @Autowired var targetJsonError: String = null

  override def configure(): Unit = {
    from(sourceJsonIn).
      to("bean:fileProcessor").
      choice().
        when(header("status").isEqualTo("ok")).
          to(targetJsonOut).
        otherwise().
          to(targetJsonError)
  }

}

Here I'm using Camel Spring support for java. The FileRouter class will receive the endpoints from the spring context in runtime. In fact, these endpoints are now spring beans defined as follows:

trait S3Beans {
  @Bean
  def sourceJsonIn = "aws-s3://json-in?amazonS3Client=#client&maxMessagesPerPoll=15&delay=3000&region=sa-east-1"
  @Bean
  def targetJsonOut = "aws-s3://json-out?amazonS3Client=#client&region=sa-east-1"
  @Bean
  def targetJsonError = "aws-s3://json-error?amazonS3Client=#client&region=sa-east-1"
  @Bean
  def client = new AmazonS3Client(new BasicAWSCredentials("[use your credentials]", "[use your credentials]"))

}

There is also the FileProcessor that handles the file content. It is also defined as a spring bean as follows:

trait NoThirdPartBeans {
  @Bean def fileProcessor() = new FileProcessor
}

The S3 endpoints,  FileProcessor and FileRouter classes are ready to be added into the spring context. As far we are using spring support from camel, they will on be available on the camel context as well. It's being done as following:

@Configuration
@ComponentScan(Array("com.example"))
class MyApplicationContext extends CamelConfiguration with S3Beans with NoThirdPartBeans {}


Now the implementation is ready to be tested. In order to achieve to behaviour I want, I need to replace all endpoints set on S3Beans class by "mocked" endpoints. By doing that, I'll be able to "control" the external dependencies and then simulate different scenarios. To do that, I'll create a different "test context"but only replacing the beans I need to mock.

@Configuration
class TestApplicationContext extends SingleRouteCamelConfiguration with NoThirdPartBeans {
  @Bean override def route() = new FileRouter
  @Bean def sourceJsonIn = "direct:in"
  @Bean def targetJsonOut = "mock:success"
  @Bean def targetJsonError = "mock:error"
}

Direct is a camel component that works as a "memory" queue. It is gonna replace the S3 bucket where the files come from. Mock is another camel component that we can assert in runtime.  They are replacing the output S3 buckets. I can now check whether they receive messages or not.
Now It's time to create the test class. It' s gonna use the"test context" I just created and then validate different test scenarios. It's being done as follows:

@RunWith(classOf[CamelSpringJUnit4ClassRunner])
@ContextConfiguration(classes = Array(classOf[TestApplicationContext]))
class SimpleTest {
  @EndpointInject(uri =  "mock:success")
  val mockSuccess:MockEndpoint = null

  @EndpointInject(uri =  "mock:error")
  val mockError:MockEndpoint = null

  @Produce(uri = "direct:in")
  val template:ProducerTemplate = null

  @Test
  def shouldHitTheSuccesEndpoiny(): Unit ={
    val fileContent =  IOUtils.toString(getClass.getResourceAsStream("/json-file.json"))
    template.sendBody(fileContent)
    mockError.expectedMessageCount(0)
    mockSuccess.message(0).body().convertToString().isEqualTo(fileContent)
    mockSuccess.assertIsSatisfied()
    mockError.assertIsSatisfied()
  }

}

Conclusion

Real world integrations can be much more complex than the example I used. But they still need to be tested somehow. Systems like these without tests will became unmaintainable soon. The test approach i used fits well on case there is routing logic or between the components being integrated.
It is also  important to notice how the spring api made the implementation simpler and testable. As It was implemented before (without spring or any DI technique) would be very hard to achieve the result.
The working example can be found here.